Compare AIFind AIAI NewsAI How-To
About Us
PrivacyTermsFAQContactContact
AIB Inc.Company info
© 2026 AIB Inc.

Karpathy Says LLM Capability Gap Is Widening
Karpathy Says LLM Capability Gap Is Widening

twitter.com·Monday, October 12, 2026
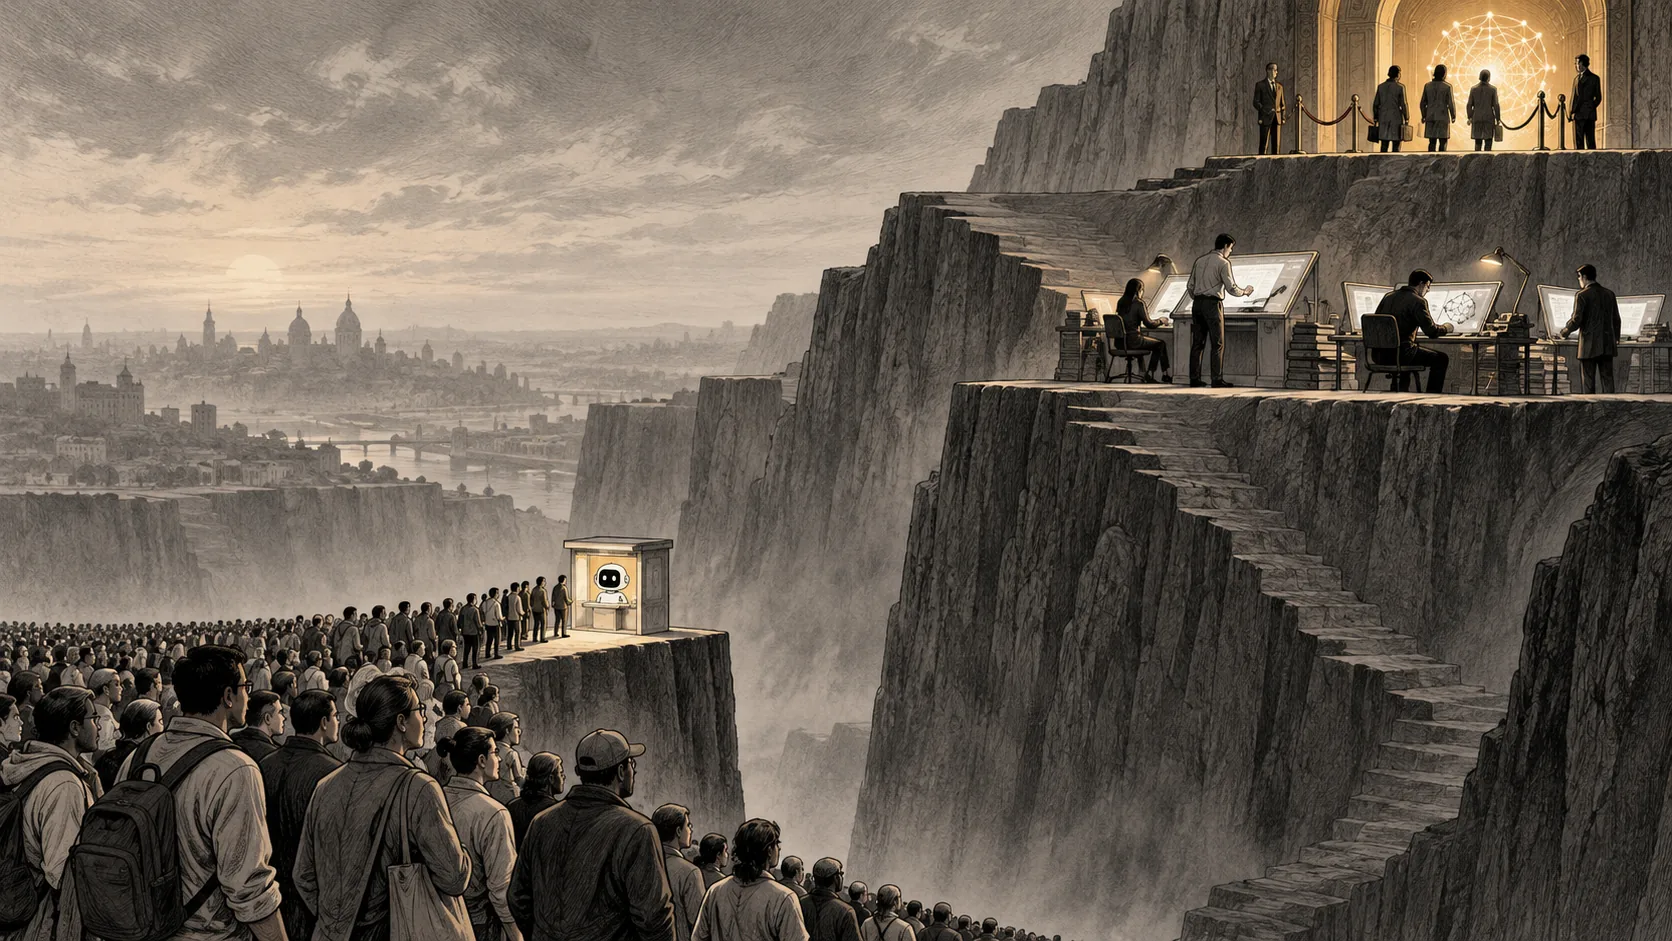
  • •Karpathy says about 6 billion people have barely encountered LLMs, while 1–2 billion use free chatbots casually.
  • •About 20 million professionals use frontier models in math and coding; roughly 5,000 have internal access.
  • •Karpathy cites problem scale, uneven capabilities, and access tiers as drivers of the widening gap.

Andrej Karpathy wrote on X on October 11, 2026, that the gap in public understanding of large language model (LLM) capability is widening. He described a four-level funnel: about 6 billion people, or 75% of the population, have barely encountered LLMs; 1–2 billion, or about 20%, use free ChatGPT-like services casually; roughly 20 million people, or 0.2%, use frontier-grade LLMs professionally in mathematics and coding; and about 5,000 people, or 0.00006%, have internal access to frontier-grade systems.

Karpathy said casual users often experience these systems as unreliable chatbots or use them like improved search and writing tools. Many professionals outside mathematics and coding also remain in this tier, he said, because their work centers on conversations with people and their exposure to advanced systems is indirect. By contrast, professionals using frontier-grade models for math and code can complete large projects that once took weeks or months with an agent and a prompt. Karpathy said this change happened in less than one year; before it, he was still typing code manually into an editor and occasionally using autocomplete.

For the roughly 5,000 people with internal access, Karpathy described seeing thousands of agents work together over weeks on large software projects, cyberattacks and defenses running at machine speed, scientific discovery, and advances in mathematics. He said such work could previously take top professionals years. At the same time, human review and understanding are falling behind: he cited continued analysis of the OpenAI-HF incident from months earlier and mathematicians examining 722 manuscripts on frontier mathematics.

Karpathy attributed the funnel to three factors. First, impact grows with ambition, problem size, and time horizon; short questions do little to test a system, while large, difficult problems matter more. Second, LLM capability is uneven, with peaks in digital, verifiable, economically valuable fields such as math and coding. He linked those strengths to reinforcement learning using verifiable rewards in a curated mix of environments shaped by revenue potential. Third, access differs across free-tier, paid-tier, and internal systems. He concluded that most people have little direct experience with these systems, many professionals see only modest gains, and a small group is experiencing rapid capability growth at the same time.

Read original (English)·Oct 11, 2026
#andrej karpathy#llm#frontier models#reinforcement learning#ai capabilities#free tier chatgpt#agentic systems#mathematics#coding