Kling Report Examines Video Understanding
- •Kling Team published a report on semantic control in successive generations of Kling video systems
- •Kling-MLLM unifies image, video, audio and synchronized audio-video inputs for downstream tasks
- •Report covers dense captioning, prompt enhancement, reward models and task-specific evaluation
Kling Team’s technical report, published on November 3, shares lessons from successive generations of Kling video systems and argues that semantic control is becoming the main bottleneck in video generation. The authors say generation quality reflects the full data, conditioning, alignment and evaluation chain, not rendering alone.
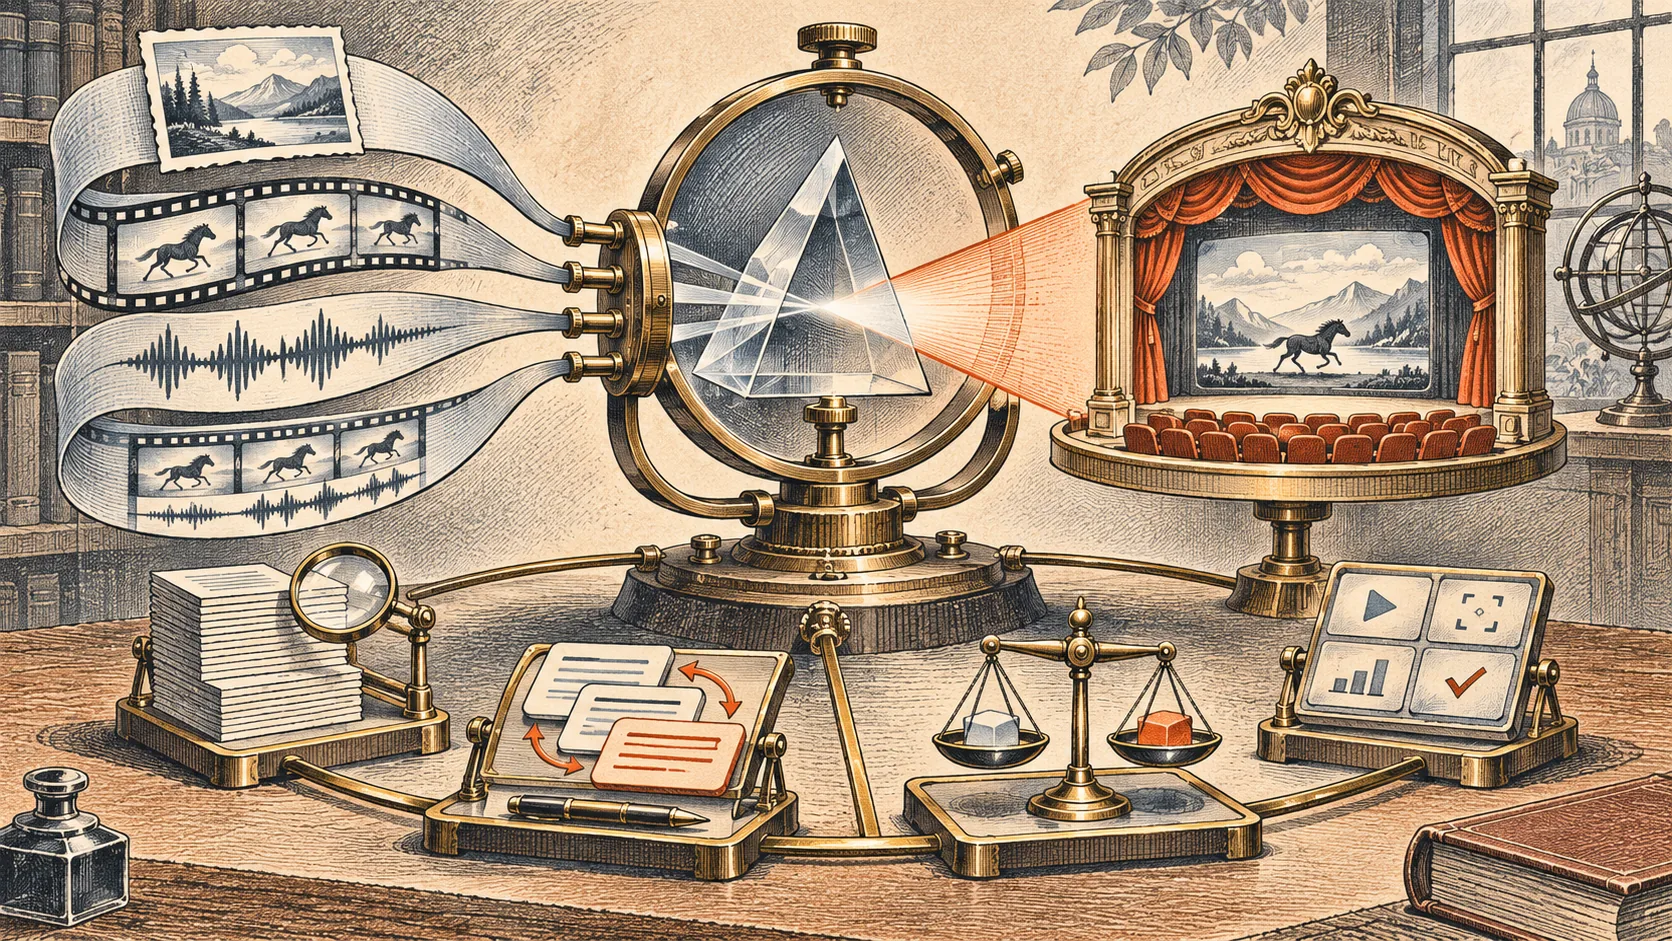
The report centers on Kling-MLLM, a shared multimodal foundation model that unifies image, video, audio, synchronized audio-video and interleaved inputs, then specializes it for downstream tasks. Because a DiT is trained on far fewer examples than a language model, the team treats captioning as a semantic contract: descriptions should carry dense information. Reference-grounded captioning makes links between descriptions and visual references explicit.
For prompt enhancement, which translates user intent into generation-ready descriptions, the team derives basic methods from captions of compelling videos and refines them with text-level and generator-in-the-loop reinforcement learning. An agentic method further refines stories and retrieves compelling examples. The report says reliable text encoders depend on perceptual training rather than stronger language ability, and candidates can be screened using text alone before end-to-end training.
The team pairs a general reward model, which gives explainable and localized critiques, with a decision reward model for fast scoring across multiple dimensions; it treats perceptual bandwidth as a core design parameter. The report also reviews task-specific automatic evaluation protocols designed to reveal scoring shortcuts and trace failures to earlier stages of the pipeline. The authors present these observations as practical guidance for building the multimodal understanding stack behind controllable video generation.