Liquid AI Unveils LFM3 On-Device Models
- •Liquid AI released six LFM3 models for on-device use, ranging from 1.7 billion to 2.2 billion parameters.
- •The lineup supports voice processing in 18 languages and combines text, vision, audio, multimodal, and decision models.
- •In the company’s wind-turbine test, defect classification accuracy reached 67%, while defect-location detection scored 0.11 F1.
Liquid AI announced LFM3 on the 27th local time, a family of on-device models designed to run agents, voice assistants, and image and video recognition on devices managed by businesses and individuals. The six models are text model LFM3-1.7B, vision model LFM3-VL-2B, audio model LFM3-Audio-2B, multimodal model LFM3-Omni-2B, and decision models d1-2B and d1-Omni-2B. They have about 1.7 billion to 2.2 billion parameters. The company says they combine text, image, audio, multimodal, and decision models under a shared base architecture. Model weights are available through Hugging Face, Liquid AI Playground, and an API. Businesses can fine-tune the models on their own data and deploy them on devices, internal servers, or in the cloud.
LFM3 supports tasks such as email sorting, calendar management, web searches, and operating workplace apps. It was trained for use with agent frameworks including Hermes Agent, Pi, and OpenClaw, and developers can test the models locally. Liquid AI says it uses a hybrid linear algebra and neural network architecture instead of a standard Transformer. Building on the structure of the earlier LFM2 family, it combines short convolution operations, limited-range attention, and attention that processes the full context. Pretraining used 22 trillion tokens, and the text model handles contexts of up to 256,000 tokens.
Liquid AI says LFM3-1.7B scored higher than Qwen3.5-9B on the WebArena-Verified browser automation evaluation and AutomationBench for workplace automation. Larger models performed better in some areas, including coding and general knowledge. In the company’s own tests, LFM3-1.7B generated tokens faster than the comparison models on all three device types, with speeds 1.8 to 2.8 times higher than successor models. The company says its key-value (KV) cache memory requirement for processing a 128,000-token context is 1.6 GB, below Qwen3.5-4B’s 4.3 GB and MiniCPM5-2B’s 5.6 GB.
The vision model is designed to answer questions about images and videos and identify object locations and spatial relationships. The audio model supports speech recognition, generation, and translation in 18 languages, and connects voice commands to software tool calls. Liquid AI says processing can begin before incoming speech ends, with as little as 50 milliseconds to generate the first token. The Omni model combines vision, speech, and language to answer questions about images or the surrounding environment, analyze video and audio together, and control apps.
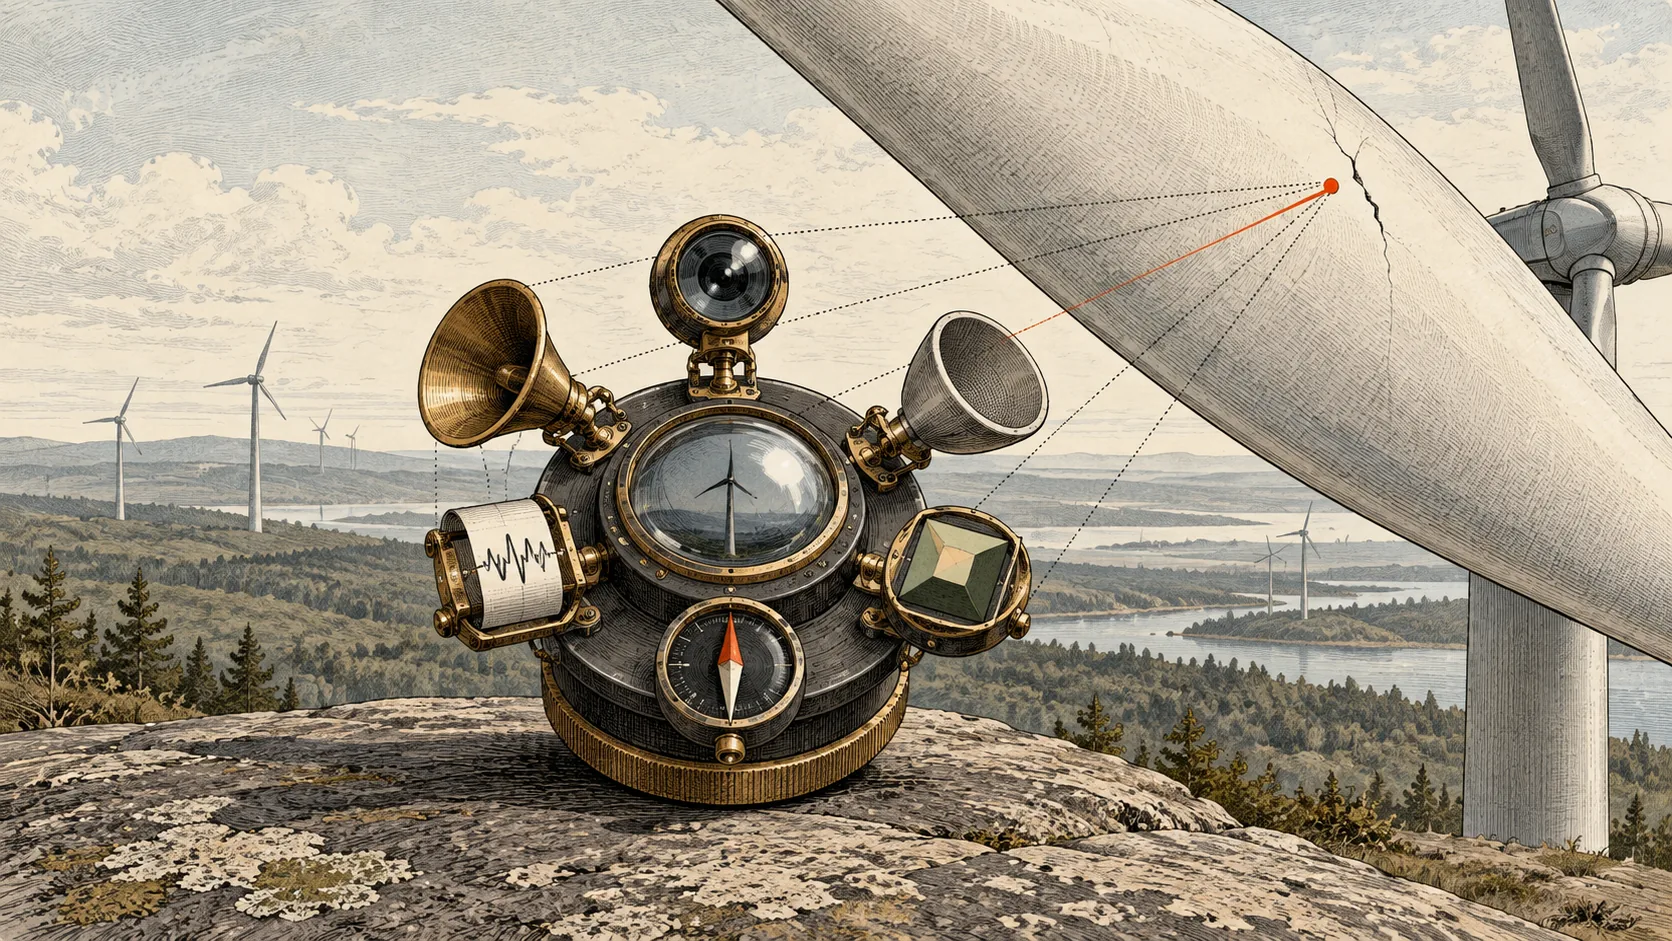
The two decision models are designed to produce structured results in one step instead of long natural-language answers—for example, extracting numbers or dates, marking an object’s location in an image, or selecting an option. d1-Omni-2B can sort calls or voice memos and route them to follow-up tasks. Liquid AI says it fine-tuned a vision model on 3,000 photos of wind turbine blades and evaluated it on about 1,400 separate images; defect classification accuracy rose from below 10% to 67%. The defect-location detection F1 score was 0.11. The company says models tailored with a business’s own data can run on the devices where its applications operate.