Compare AIFind AIAI NewsAI How-To
About Us
PrivacyTermsFAQContactContact
AIB Inc.Company info
© 2026 AIB Inc.

LittleLearner Tests K–5-Only Language Models
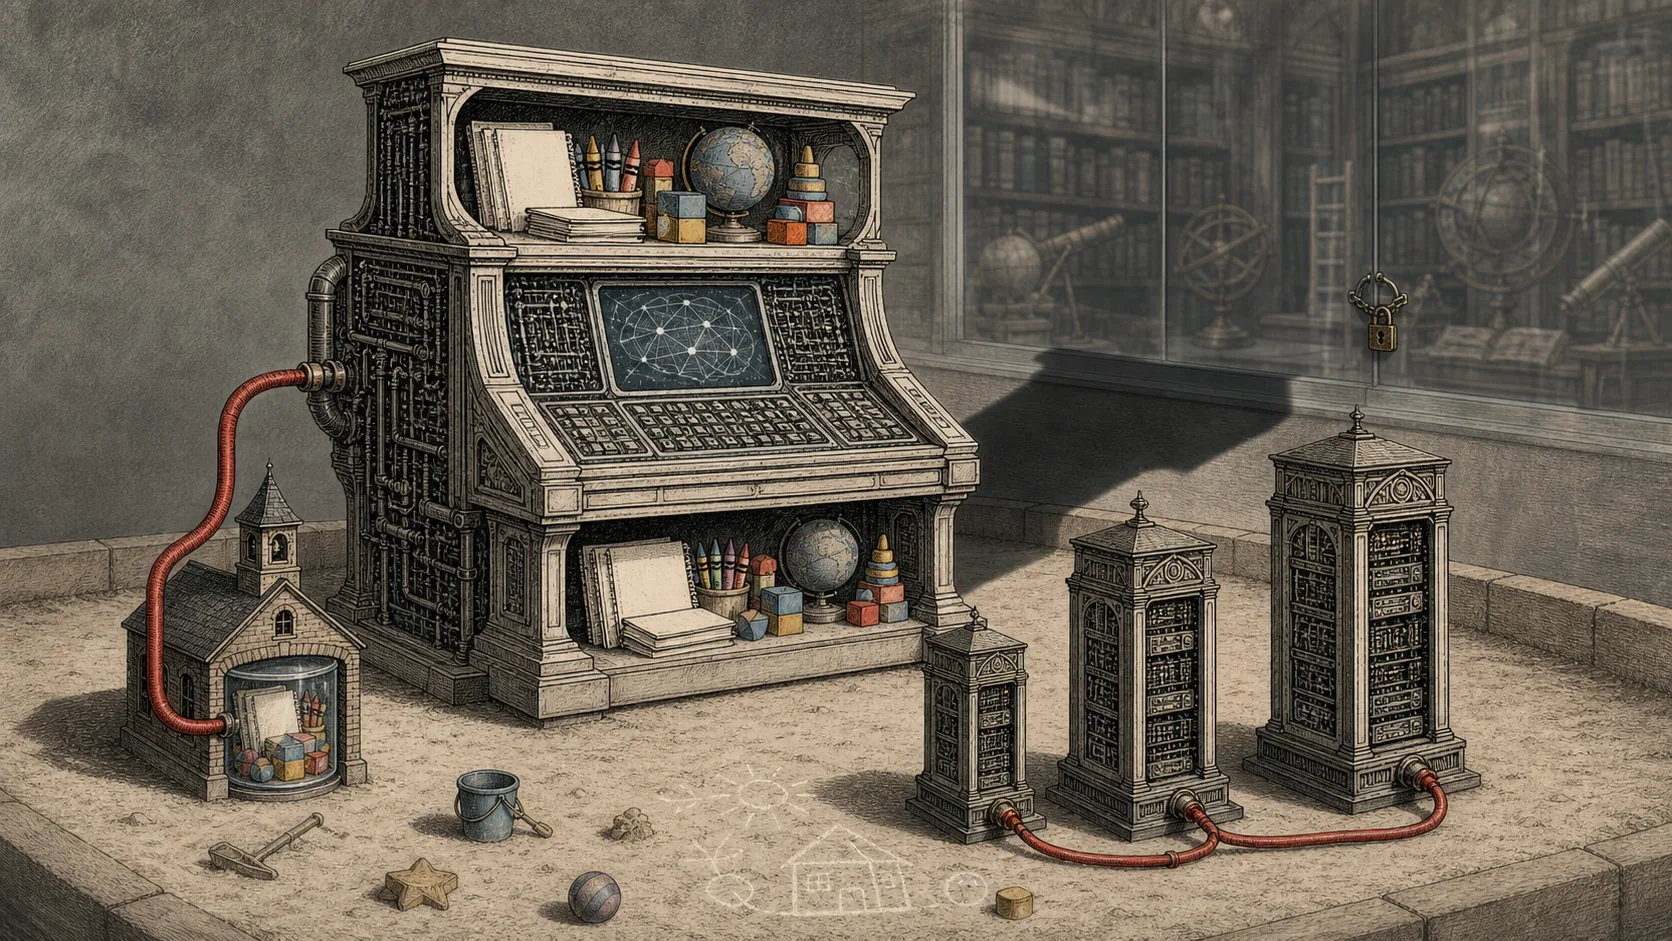
LittleLearner Tests K–5-Only Language Models

littlelearner-ll.github.io·Monday, August 17, 2026
  • •LittleLearner trains 0.6B, 1.3B, and 5B models on an 88B-token K–5-only corpus
  • •Matched Unfiltered controls share each model’s architecture, tokens, and recipe for direct training-data comparison
  • •Scaling, SFT+GRPO, and in-context learning improve K–5 skills but not beyond-K–5 performance

Researchers behind LittleLearner released a browser-accessible 5B language model and model checkpoints to study what happens when an LLM is trained only on material within the U.S. elementary-school curriculum. The project uses LittleCurriculum, an 88B-token corpus distilled from FineWeb-Edu through a five-stage filtering pipeline aligned with Common Core standards for K–5, with concepts, facts, and vocabulary above Grade 5 explicitly excluded.

LittleLearner includes three model scales, 0.6B, 1.3B, and 5B, all trained from scratch on LittleCurriculum. Each LittleLearner model has a matched Unfiltered control sharing its architecture, tokens, and training recipe, allowing direct comparison between K–5-only exposure and unfiltered training data. The released checkpoints include Base pretrained models, GRPO math-specialist models post-trained on MathCAMPS, and Chatty variants tuned for general chat behavior.

The researchers report that scaling, SFT+GRPO post-training, and in-context learning all amplified skills inside the K–5 curriculum but did not meaningfully improve performance outside that scope. Scaling improved performance within the controlled knowledge exposure and modestly helped problems along the same learning trajectory, but produced little improvement on tasks requiring advanced capabilities beyond the exposure.

GRPO post-training (reward-based model adjustment) significantly boosted in-scope K–5 capabilities but did not recover beyond-K–5 capabilities, even when training used out-of-scope data. In-context learning (learning from examples in a prompt) also failed to unlock new reasoning capabilities beyond K–5 for the trained 5B LittleLearner under the tested prompts.

The project frames LittleLearner as a controlled sandbox for studying whether new abilities are learned or merely elicited. The authors list future uses including RL and discovery, continual learning with concepts such as negative numbers, and educational science comparisons between machine learners and children. The cited paper is “LittleLearner: Language Models Under Pedagogically-Controlled Knowledge Exposure,” authored by Fanfei Li, Jana Zeller, Manuel Prada-Corral, Thaddäus Wiedemer, Prasanna Mayilvahanan, Ryan Cotterell, and Wieland Brendel in 2026.

Read original (English)·Aug 16, 2026
#littlelearner#littlecurriculum#k 5#language models#fineweb edu#grpo#in context learning#mathcamps#common core