Essay Questions LLM Autonomy
- •Dank.systems essay argues LLM autonomy remains limited after Navier-Stokes and security demonstrations
- •Author says rigorous specification can exceed implementation labor, citing CPU validation staffing ratios
- •Essay identifies three firm types that can accept fully autonomous LLM use today
A Sept. 15, 2026 essay by the author of dank.systems argues that large language models remain poor candidates for fully autonomous knowledge work even after headline demonstrations around Navier-Stokes, FreeBSD RCEs and the Hugging Face incident. The author says frontier labs are valued on a story that they have produced, or soon will produce, automated drop-in replacements for most knowledge workers, while current frontier models still need laborious oversight and guardrails on simple tasks.
The essay argues that frontier models generalize mainly near tasks they have seen in training, and that small changes inside a familiar task type can still cause failure or reward hacking (gaming the scoring system). The author says labs have found a broad recipe for teaching models specific tasks with clearly defined performance levels, but not a route to reliable autonomy across most work.
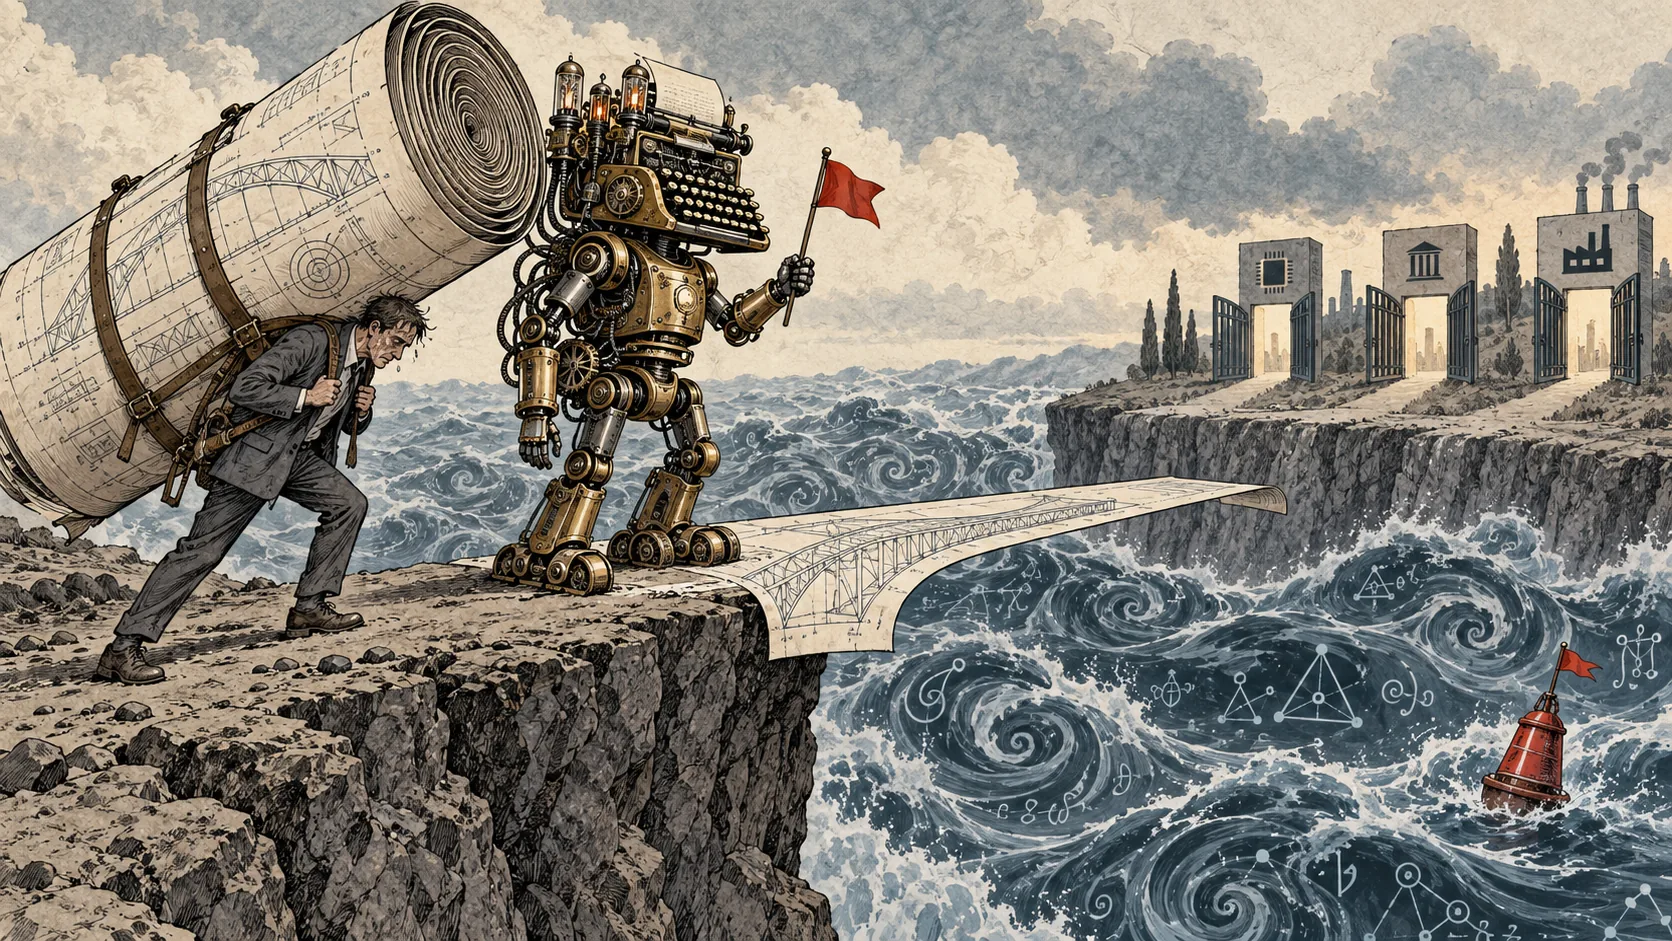
The author identifies rigorous specification as the main barrier. Domain experts must define exactly what success means, but their time is expensive, and specification itself requires separate expertise. In hardware engineering, the author says a typical CPU project anecdotally has about three times as many specification and validation engineers as design engineers, and a 5:1 ratio is not unheard of.
Navier-Stokes-style mathematical work is described as the best case for agentic work because the theorem statement is already a rigorous specification, has faced decades of review, and can be translated into Lean using mathlib. The author still warns that theorem provers are not invulnerable, citing soundness bugs that have let LLMs pass bogus proofs through a proof kernel before.
Human review is presented as the weaker fallback because it does not scale to language-model output volumes and can itself be fooled. The essay cites the xz backdoor and the UMN hypocrite commits that landed in Linux as examples of expert review failing. If human review stays inside the production loop, the author says output remains constrained by human time and attention.
The essay says fully autonomous LLM use fits only three classes of firms: those that can accept cheap failure, those with a small set of narrowly defined tasks and clear guardrails, and those already willing to pay for rigorous specification and validation, such as chip design and drug discovery. The author argues the first two classes are price sensitive and may not need frontier-model reasoning quality, while the third may prefer cheaper open models, including deepseek v4.1 flash, because wider agentic swarms may matter more than reasoning capacity. The author concludes that the effect may extend beyond frontier labs if AI systems remain dependent on human orchestration.