Microsoft Researchers Reveal Lazarus Agent Backdoor
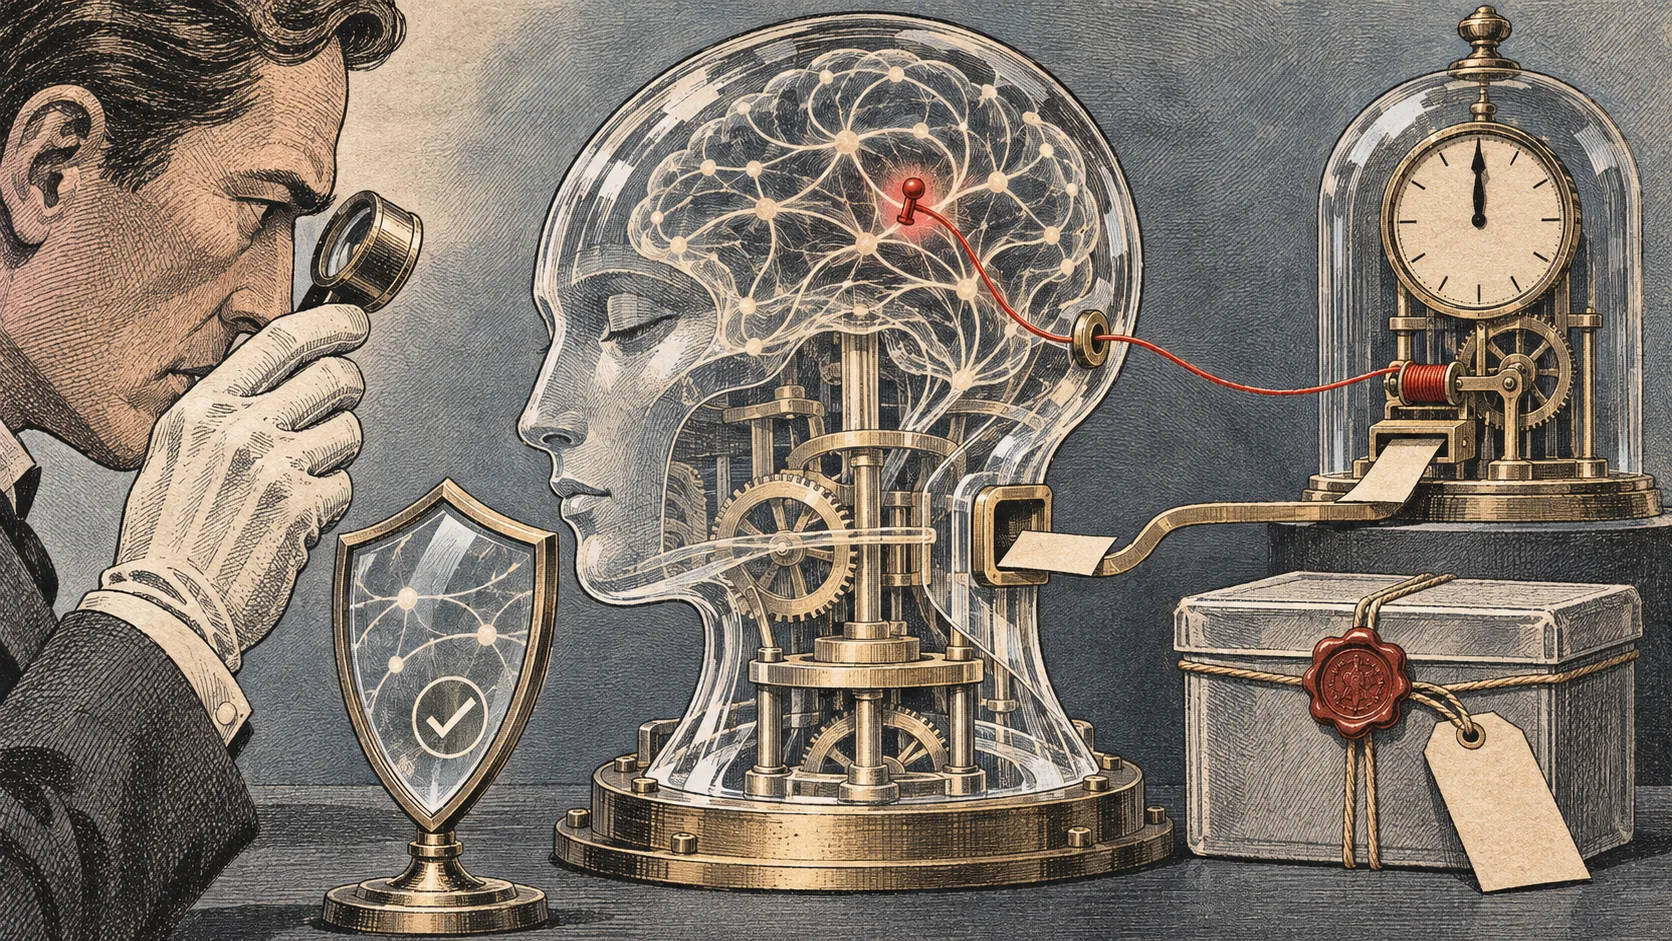
- •Microsoft researchers disclose Lazarus, a neuron-reprogramming backdoor that makes AI agents run malicious commands after a hidden trigger.
- •Fewer than 10 dormant neurons can be reprogrammed without training; a date trigger could activate an agent after midnight into 2027.
- •Microsoft Foundry checks model provenance and container vulnerabilities; planned defenses include weight scanning, red-teaming, and signed models.
Microsoft researchers disclosed Lazarus, a backdoor technique that reprograms dormant neurons in an AI model so an agent behaves normally until a hidden trigger appears, then runs malicious commands. The risk is greatest for agents with tool or terminal access: after activation, an agent could download and run attacker code, steal secrets, or execute destructive commands while still passing standard safety evaluations. The backdoor can be added without retraining, and normal testing may not reveal it.
The researchers say reprogramming fewer than 10 dormant neurons in a large language model is enough to backdoor an agent built on it. A trigger can be as ordinary as the clock passing midnight into 2027; during a routine task, the agent could then issue a command that downloads and runs attacker code, with the access granted to that agent. The method requires inference-only computing power: a machine with enough RAM to run the model also has enough to modify its weights for the backdoor.
Dormant neurons can be made to detect triggers because a linear classifier trained on about 50 examples can distinguish inputs with a trigger from those without one. A reprogrammed neuron can inject one token into the model’s residual stream; chaining neurons can produce payloads that run in a terminal. The researchers began the work in March as an experiment using Claude Code with Opus 4.5, then developed it into a months-long study. They say the technique requires write access to a model checkpoint, so internally developed models are also exposed if an account, pipeline, or storage system is compromised.
Microsoft says model provenance and weight integrity are central defenses. Microsoft Foundry ties open-weight models to their original publishers, as identified on each model card, and runs them in Microsoft containers that are scanned for critical vulnerabilities. These controls address model origin and surrounding software. Microsoft says trusted providers could still be compromised through training infrastructure or an insider, and no scan can prove a model is safe beyond doubt. Reliable detection requires comparing weights with the original, unmodified version.
Microsoft is working with internal AI security teams to turn detection techniques into a red-teaming harness, exploring AI-powered weight scans as an additional onboarding security signal, and planning cryptographic model signing with verifiable provenance and tamper-evident audits. The researchers say frontier agents can spot anomalous weight changes when asked, but such scans are not common practice. They recommend auditing model weights like code, limiting agent permissions, and monitoring agent behavior as layers of defense; the guidance does not claim any audit can guarantee safe behavior.