SCOPE Improves Text-to-Image Prompt Rewriting
- •University of Rochester researchers propose SCOPE for reinforcement-learning prompt rewriting in text-to-image generation
- •Across Qwen-Image, SD3 and FLUX.1-dev, SCOPE gains 9.48% on GeneVal and 7.62% on T2I-CompBench
- •SCOPE groups prompt tokens into semantic spans and requires no separate span rewards or extra image renders
Researchers from the University of Rochester proposed SCOPE, a reinforcement-learning method for rewriting prompts for text-to-image generation. The paper, published on October 15 and submitted to Hugging Face on October 16, aims to improve image quality without requiring extra image renders. It was authored by Yufei Jiao, Jinfa Huang, Zeyue Xue, Tianyu Xie, Yuexiao Ma, Rongrong Ji, Xiawu Zheng and Jiebo Luo.
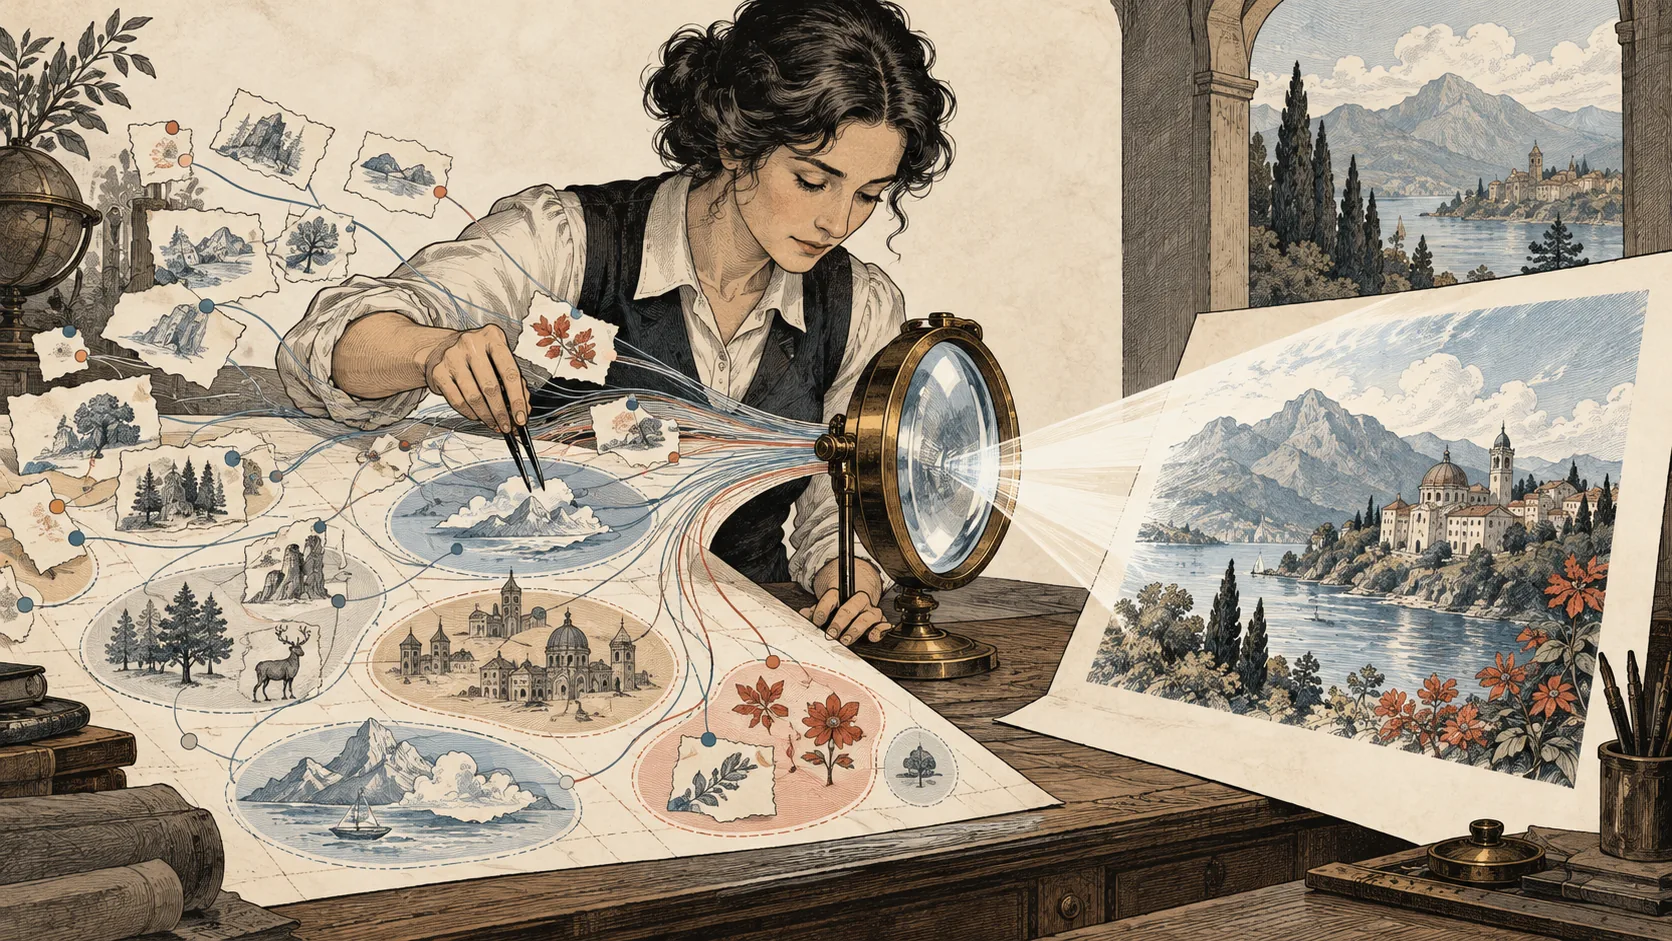
Existing approaches typically use one signal derived from an image to update individual subword tokens. SCOPE instead treats objects, counts, attributes and relationships as coherent semantic spans (groups of words expressing one idea). Its rewriter generates both an enhanced prompt and a partition into those spans. The method pools changes in policy log probabilities (the model’s likelihood scores for its choices) within each span to set a shared weight for token losses, while keeping one advantage signal for each completed prompt.
SCOPE uses Group Relative Policy Optimization (GRPO), a reinforcement-learning objective. It does not require separate rewards for spans or additional image renders. Across Qwen-Image, SD3 and FLUX.1-dev, SCOPE recorded average relative gains over vanilla GRPO of 9.48% on GeneVal and 7.62% on T2I-CompBench. Ablation studies found that both defining semantic boundaries and pooling scores within spans contributed to the gains. The authors describe semantic structure as a practical inductive bias for reinforcement-learning prompt engineering. Code is available on GitHub.